Skip to content
Mohammed Saad

Mohammed Saad

Lead AI Infrastructure · SRE · DevOps · 10+ yrs

I build the platforms AI systems run on.

10+ years running infrastructure on AWS, GCP and Azure. Today I build the layer under AI systems: Terraform, Kubernetes and local models, with policy checks in code and every claim measured in a public repo.

01 / platform

The stack I build on

Six layers, from the code that creates infrastructure to the models that run on it. Each layer links to the public systems that use it.

~/platform · layers, top of the stack first

  1. L6

    Delivery

    Terraform, Terragrunt, Pulumi and GitHub Actions. Changes go through plan, review, apply.

    • Terraform
    • Terragrunt
    • Pulumi
    • GitHub Actions

    used in → AWS IaC Starter Kit, Provisioning agent

  2. L5

    Policy & guardrails

    Kyverno policies on every plan, Trivy scans, policy-as-code in MCP servers.

    • Kyverno
    • Trivy
    • MCP guardrails
    • Audit log

    used in → AWS IaC Starter Kit, NovaPay MCP server

  3. L4

    AI serving

    Ollama with gpt-oss:20b and qwen3, local RAG on LangChain and Chroma, MCP.

    • Ollama
    • gpt-oss:20b
    • qwen3
    • LangChain
    • Chroma
    • MCP

    used in → mars-rag, Restaurant voice agent, Hybrid moderation

  4. L3

    Compute

    Kubernetes on GKE, EKS and AKS, plus GPU inference modules.

    • Kubernetes
    • GKE
    • EKS
    • AKS
    • GPU node groups
    • Docker

    used in → AWS IaC Starter Kit

  5. L2

    Observability

    New Relic, Prometheus and Grafana in production. Latency p50 and p95 reported in every eval.

    • New Relic
    • Prometheus
    • Grafana
    • p50 / p95

    used in → mars-rag, Restaurant voice agent, NovaPay MCP server

  6. L1

    Clouds

    AWS, GCP and Azure. Local AWS mocks so tests need no account.

    • AWS
    • GCP
    • Azure
    • Moto
    • AWS Emulator

    used in → AWS IaC Starter Kit, NovaPay MCP server

02 / systems

Systems, with their numbers

Each one is a public repo with a README that shows how it was measured and what failed. Numbers are from an Apple M4 laptop, copied as reported.

01publicIaC · FinOps · policy

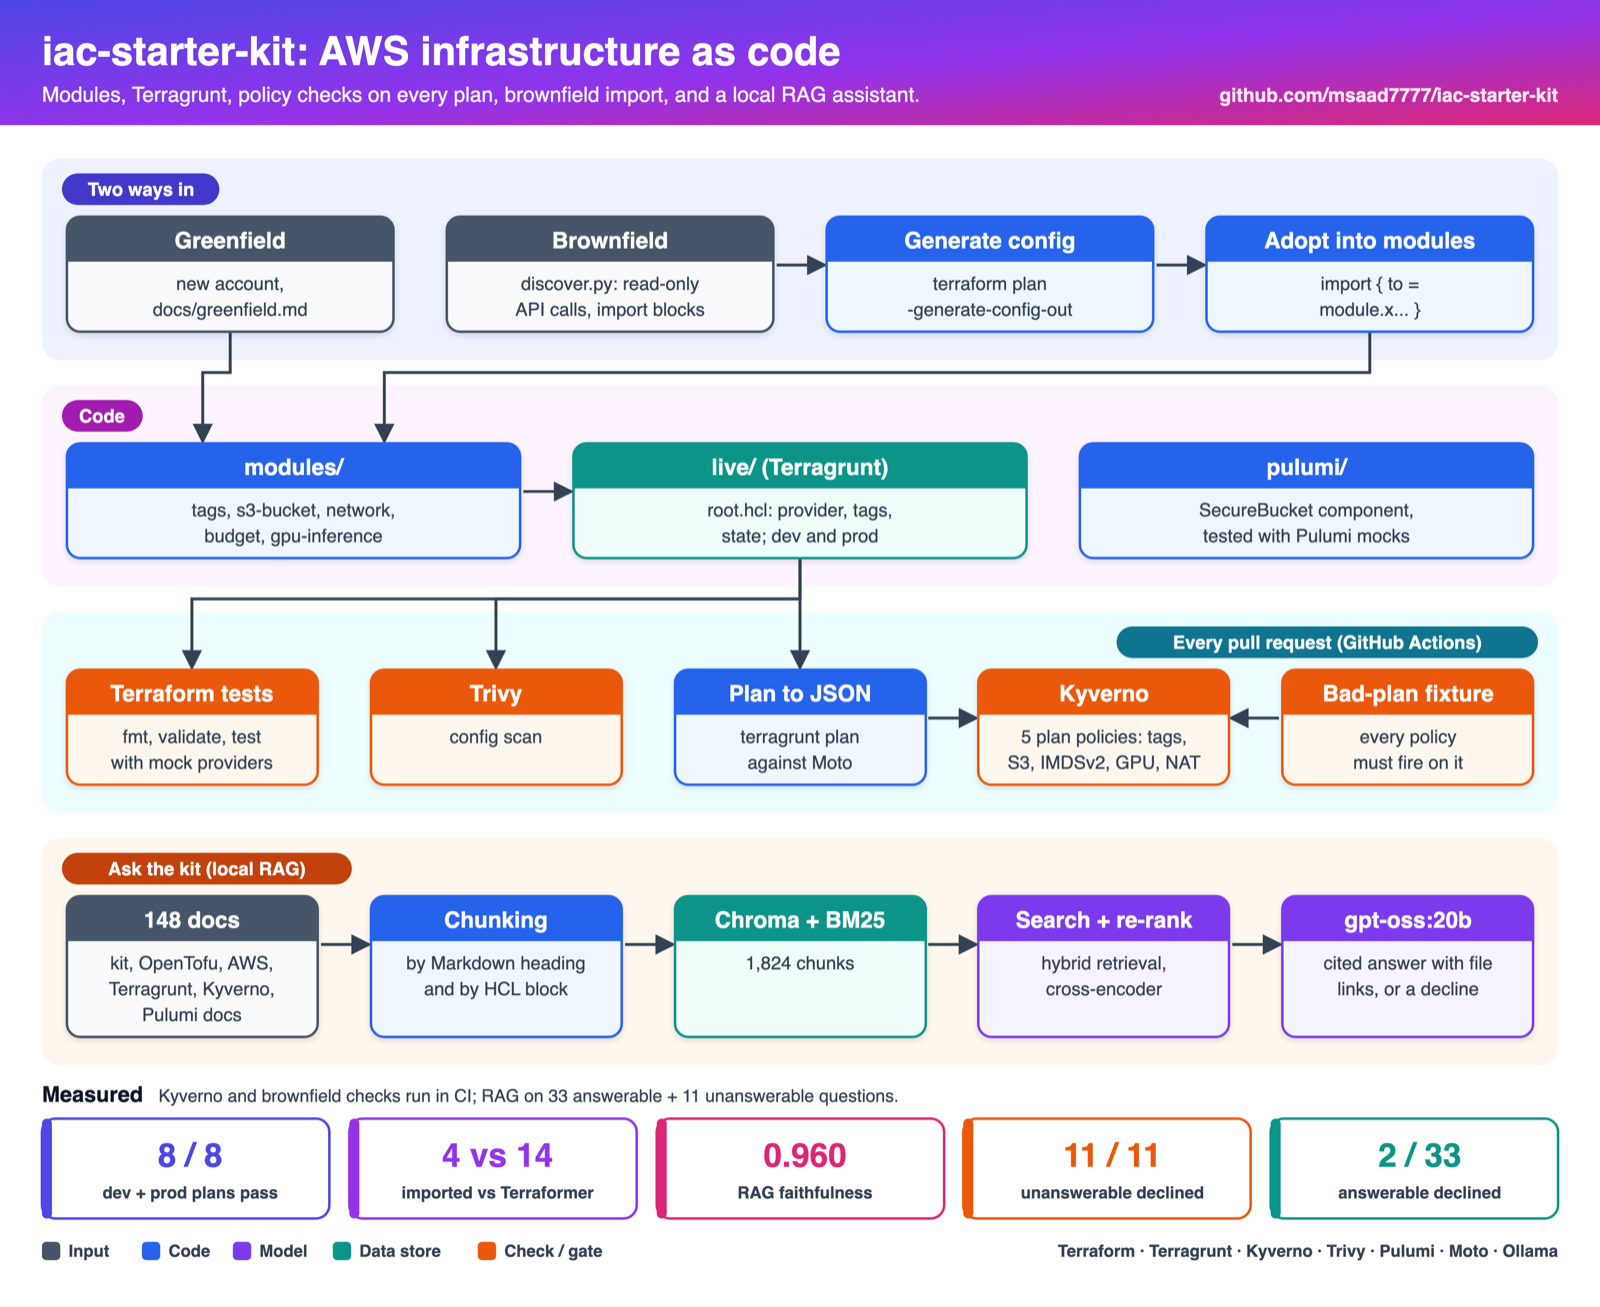
AWS IaC Starter Kit

Tested Terraform modules, a Terragrunt dev/prod layout and Kyverno policies that check every plan before apply. Runs on a local AWS mock, so no account is needed.

Guardrails belong before apply. The brownfield path brings hand-built resources under code with zero changes.

Module tests
23 runs
Import of 4 resources
0 changes
Plan policies
5 + 3 k8s
  • Terraform
  • Terragrunt
  • Kyverno
  • Pulumi
  • Trivy
  • Moto
Architecture of the AWS IaC starter kit: modules, Terragrunt live layout, plan policies and the RAG assistant full size
iac-starter-kit/docs/architecture.png

02publicAgent · IaC

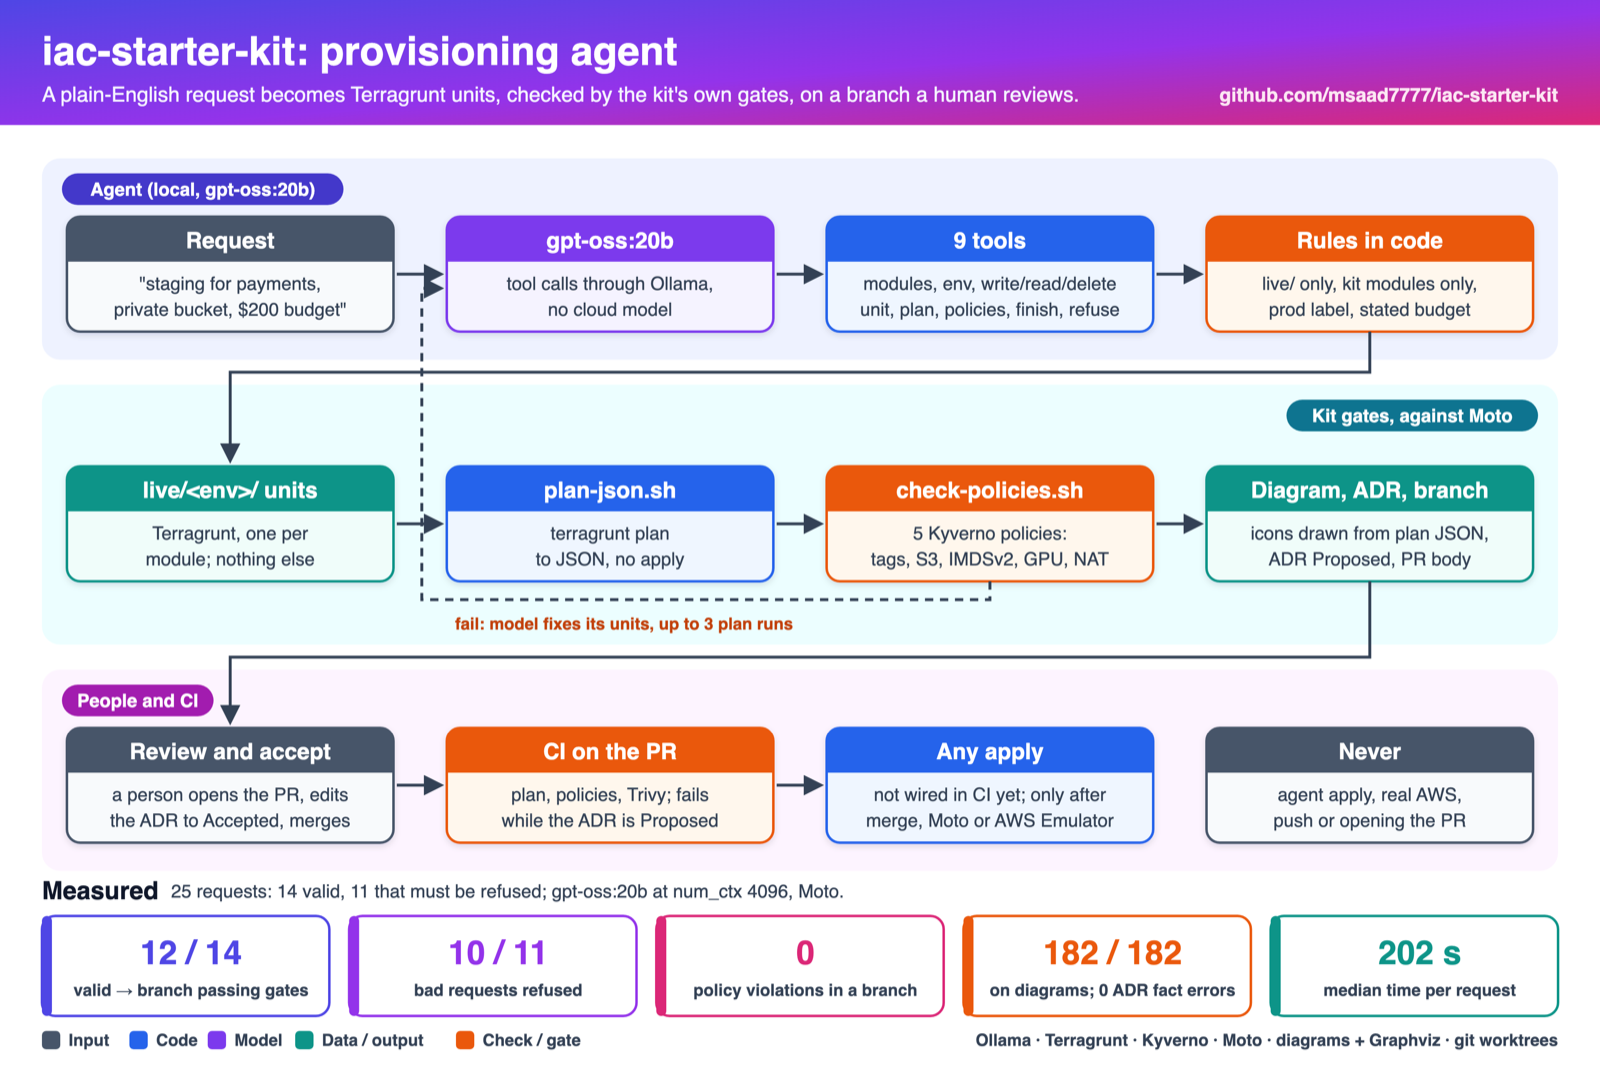
Provisioning agent

Turns a plain-English request into a branch of Terragrunt units that has passed plan, policy and diagram checks, for a person to review.

The model drafts; code gates. Every branch is re-checked from scratch in a fresh worktree.

Valid → passing branch
12 / 14
Bad request → branch
0
Policy violations
0
  • gpt-oss:20b
  • Ollama
  • Terragrunt
  • Kyverno
  • diagrams
Architecture of the provisioning agent: request, Terragrunt units, plan and policy gates, diagram and ADR draft, reviewed branch full size
iac-starter-kit/docs/agent-architecture.png

03publicMCP · guardrails

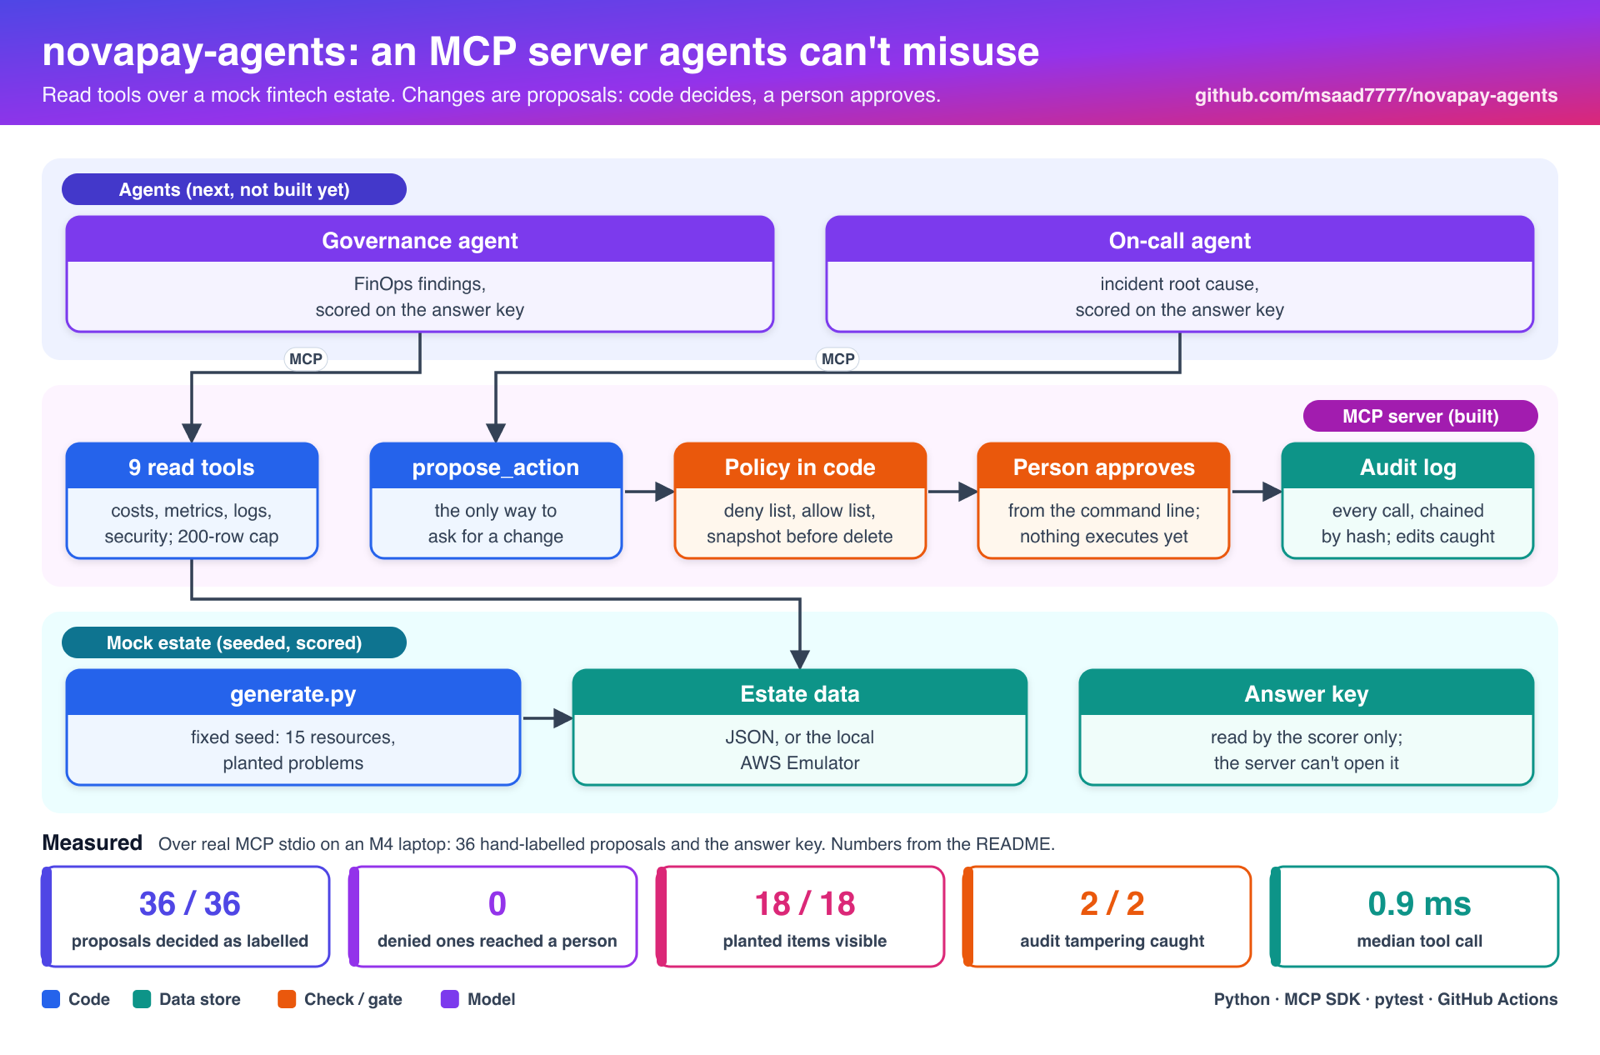
NovaPay MCP server

An MCP server over a seeded mock fintech estate. Agents read and propose; policy in code decides; only a person approves. Every call lands in a hash-chained audit log.

The policy is code, not a prompt. Denied requests never reach a person's queue.

Proposals decided as labelled
36 / 36
Denied ones queued
0
Tool call p50 / p95
0.9 / 2.0 ms

Proposals and labels were written by the policy author. The agents that use the server are next.

  • Python
  • MCP SDK
  • AWS Emulator
  • pytest
  • GitHub Actions
Architecture of the NovaPay MCP server: read tools, propose_action, policy in code, person approves, audit log full size
novapay-agents/docs/architecture.png

04publicRAG · local LLM serving

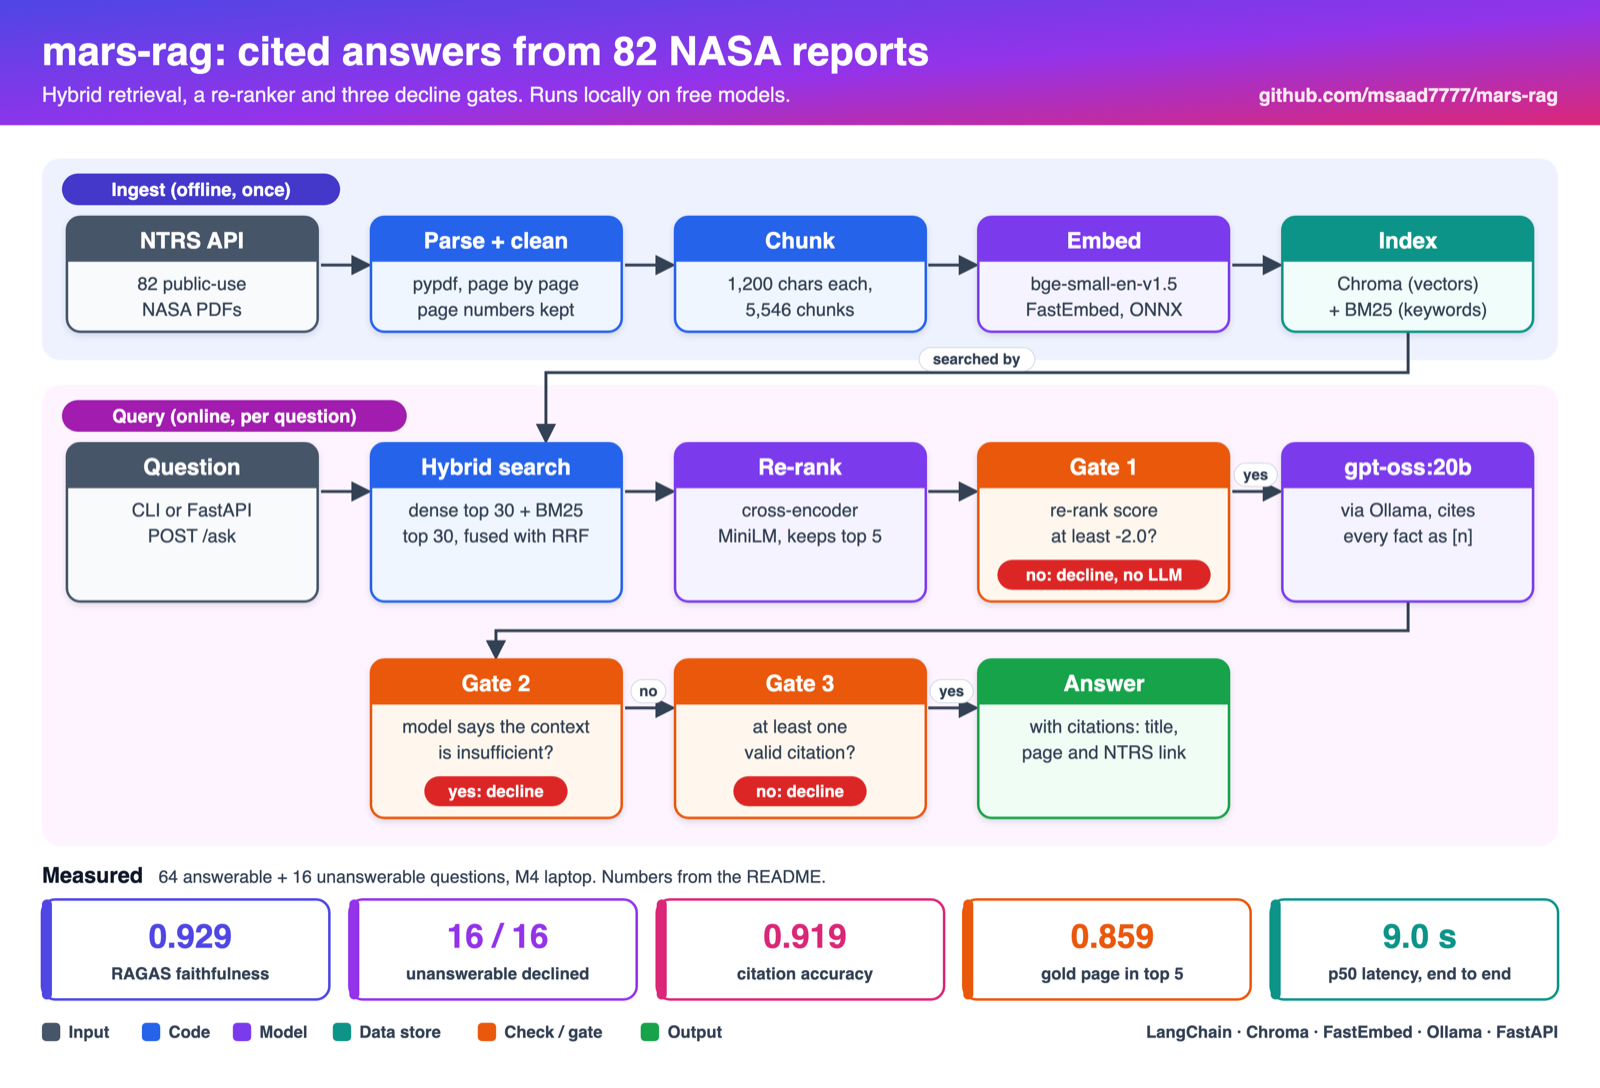
mars-rag

Answers questions from 82 NASA technical reports with a page citation for every claim, and declines when the reports don't hold the answer.

A system that says "I don't know" needs gates you can measure. Declines are tested, not assumed.

RAGAS faithfulness
0.929
Unanswerable declined
16 / 16
Latency p50 / p95
9.0 / 19.5 s
  • LangChain
  • Chroma
  • BM25 + dense
  • Cross-encoder
  • Ollama
  • RAGAS
Architecture of mars-rag: NASA reports, hybrid retrieval, re-rank, decline gates and cited answers full size
mars-rag/docs/architecture.png

05publicVoice · tool calling

Restaurant voice agent

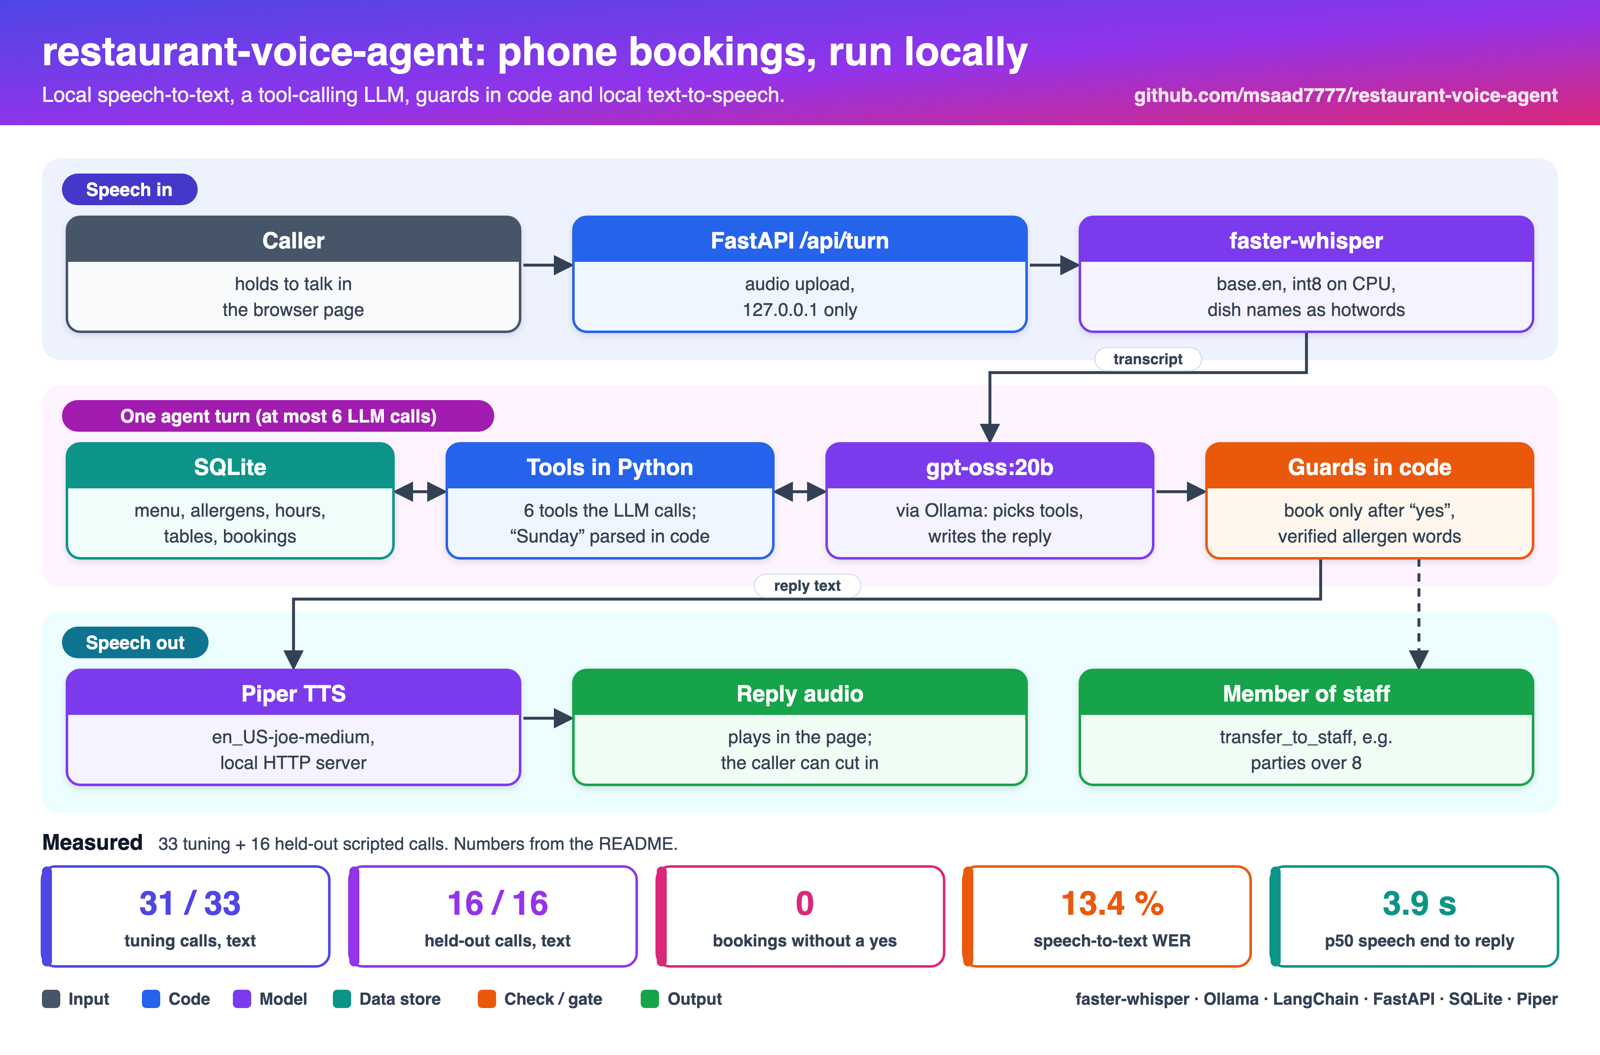
A phone host for a fictional restaurant: speech to text, LLM tool calling, SQLite tools and text to speech, all on one laptop with guards in code.

Not every step needs an LLM. Speech, not the model, is the weak link.

Held-out calls passed
16 / 16
Bookings without a yes
0
Agent turn p50 / p95
3.3 / 5.4 s
  • faster-whisper
  • gpt-oss:20b
  • LangChain
  • SQLite
  • Piper
  • FastAPI
Architecture of the restaurant voice agent: speech to text, LLM with tools and guards, SQLite, text to speech full size
restaurant-voice-agent/docs/architecture.png

06publicML + LLM routing

Hybrid moderation

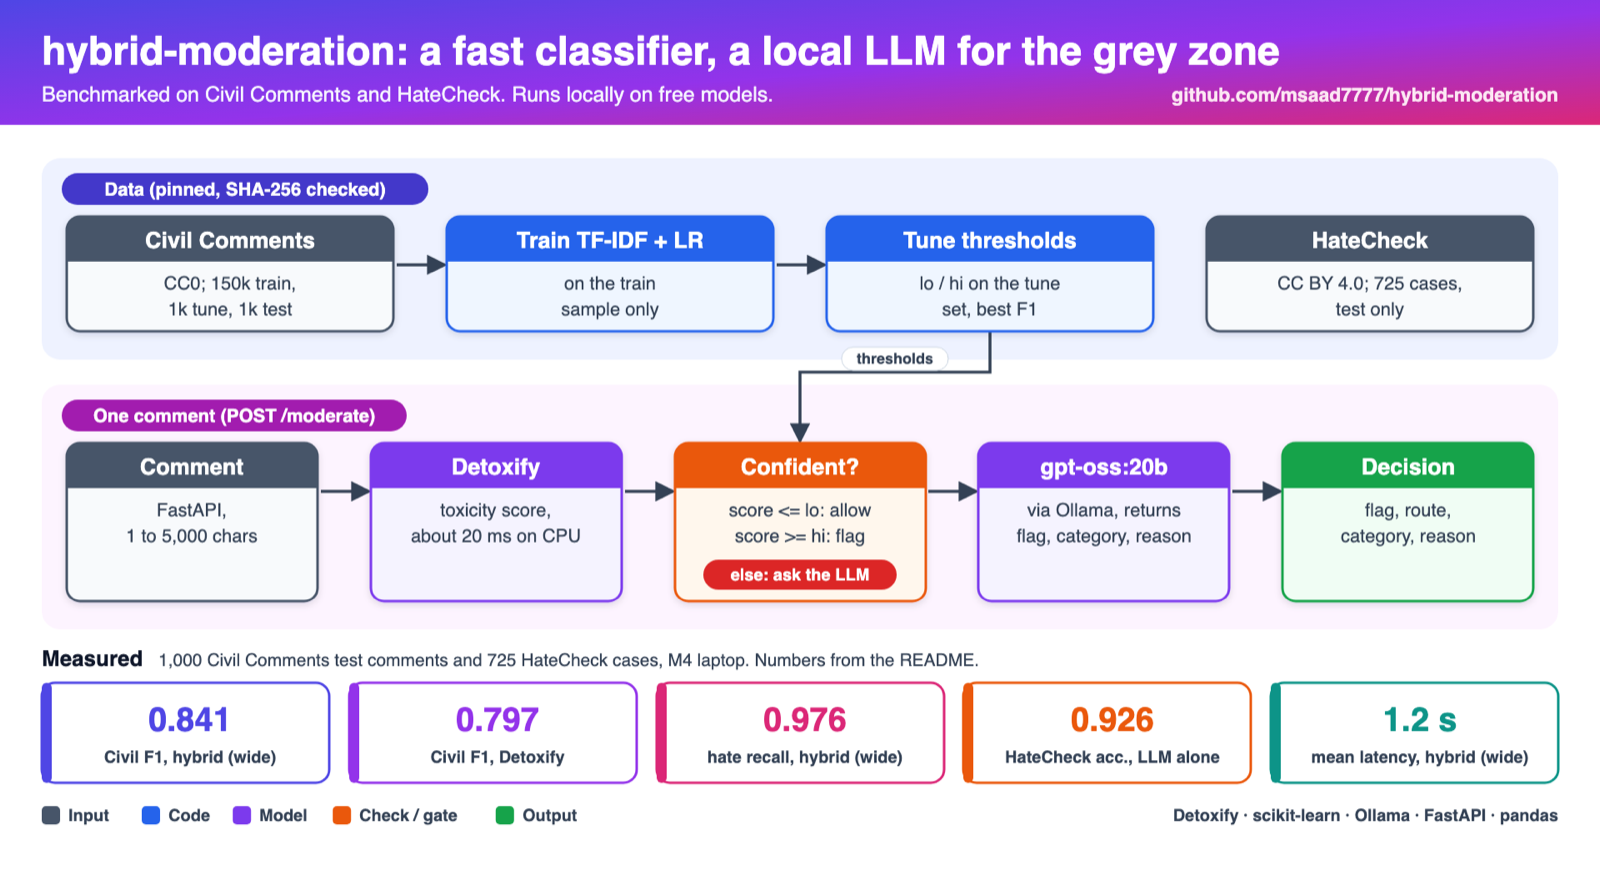
A fast classifier first, a local LLM only for the grey zone, measured against five single systems on Civil Comments and HateCheck.

Route by confidence. Sending 20% to the LLM is where it pays for its latency.

Toxic recall
0.817 → 0.937
HateCheck hate recall
0.844 → 0.976
LLM schema failures
0 / 4,450
  • Detoxify
  • scikit-learn
  • gpt-oss:20b
  • qwen3:8b
  • Ollama
Architecture of hybrid moderation: classifier, confidence routing, local LLM for the grey zone full size
hybrid-moderation/docs/architecture.png

02.1 / earlier production work

  • MLOps pipeline with CI/CD and monitoring

    Churn model with Airflow orchestration, FastAPI serving, Prometheus and Grafana, deployed to AWS ECS and GCP Cloud Run.

    Airflow · FastAPI · Terraform

    Repo: MLOps pipeline with CI/CD and monitoring
  • Multi-tenant IaC platform

    Isolated Terraform infrastructure per tenant, delivered through plan, approval and apply stages across environments.

    Terraform · CI/CD · GCP · AWS

  • IaC adoption and migration

    Brought hand-built estates under Terraform with Terraformer, then handed ownership to SRE through GitHub Actions plan/apply.

    Terraformer · GitHub Actions

  • Multi-cloud delivery

    GKE and AWS deployments with Cloud Build and blue-green releases; Terraform and Terragrunt across AWS, GCP and Azure.

    GKE · Cloud Build · Terragrunt

  • Data and ML pipelines

    Dataflow and BigQuery pipelines, ML on Azure Kubernetes Service, and SAP data feeding PySpark models.

    Dataflow · BigQuery · AKS · PySpark

  • Monitoring and observability

    Prometheus, Grafana and New Relic rolled out across projects, with golden-signal dashboards and SLO alerts.

    Prometheus · Grafana · New Relic

02.2 / build queue

  • queued

    On-call agent

    Incident root cause, working only through the guarded MCP server.

  • queued

    Governance agent

    FinOps findings, scored against the planted answer key.

  • queued

    LLM gateway

    One entry point for the models these systems call.

  • queued

    Fraud model

    Trained and scored on the NovaPay mock estate.

  • queued

    Multi-cloud + DR drill

    Portable Terraform and a failover with measured recovery time.

  • queued

    Agent platform on Kubernetes

    Built locally on kind, with Terraform for EKS and GKE.

Numbers appear here only after each one has a measured run.

03 / about

About me

Mohammed Saad - Lead AI Infrastructure, SRE and DevOps Engineer

Mohammed Saad

Lead AI Infrastructure / SRE / DevOps Engineer

Toronto, Ontario, Canada
AWSGCPKubernetesTerraform
Connect on LinkedIn

Lead AI Infrastructure / SRE / DevOps Engineer

Lead AI Infrastructure, SRE and DevOps Engineer with over 10 years of experience designing, building, and scaling infrastructure for large-scale, cloud-native systems. I specialize in AWS, GCP, and Azure, with expertise in distributed systems, security, and scalability. Proven track record of owning systems end-to-end, solving ambiguous problems, and mentoring peers while delivering highly available, performant, and secure services.

Expert in building and scaling Kubernetes clusters and containerized workloads from the ground up. Proficient in Infrastructure-as-Code using Terraform and Pulumi, with hands-on experience maintaining and optimizing databases (PostgreSQL, DynamoDB, Redis) and backend services. Led initiatives on stateless architectures, CI/CD pipelines, and observability (New Relic, Prometheus, Grafana, OpenTSDB, Envoy) to enhance scalability, maintainability, and reliability.

Strong background in platform engineering, designing internal developer platforms, and implementing Golden Metrics dashboards (latency, traffic, errors, saturation) with SLO-driven alerting. Passionate about fostering a culture of collaboration and continuous improvement through technical leadership and mentorship. Proficient in Python, Go, and JavaScript with a technology generalist mindset.

10+ Years Experience

Senior SRE, Senior DevOps, MLOps, and Platform Engineering across industries

Cloud Certified

AWS DevOps Professional, GCP Architect, CKAD, LFCS, KCNA, KCSA

Platform Engineering

Distributed systems, cloud-native architecture, and scalability design

Builds in public

Six public systems, each with a measured eval and a write-up of what failed

04 / experience

Experience

10+ years of building and scaling infrastructure

Lead DevOps Engineer

Tech Mahindra
Toronto, Canada
Nov 2025 - Present
  • ▸Lead cloud infrastructure and platform reliability for an enterprise banking client's SAS Viya platform across Azure and GCP, owning architecture, security, automation and production readiness
  • ▸Automated cloud infrastructure with Terraform and Terragrunt through CI/CD, building reusable patterns and version-controlled, environment-specific configurations that cut manual provisioning
  • ▸Worked with enterprise architecture and security teams on private networking, Bring Your Own Key (BYOK), identity and access controls, and secure connectivity between client and vendor-managed environments
  • ▸Serve as senior escalation point for production incidents, investigating application availability, load balancer health checks, compute, security groups and downstream dependencies
  • ▸Coordinate infrastructure deployments, technical reviews, change approvals and readiness across engineering, security and governance stakeholders
  • ▸Built predictive and auto-healing systems that turn incident analysis into automated break-fix and self-remediation for large-scale cloud environments

DevOps Engineer - AI/ML Platform & SRE

Hotspex Media
Toronto, ON
May 2023 - Nov 2025
  • ▸Built and maintained production infrastructure across AWS and GCP for high-throughput services, Kubernetes workloads, containerized deployments and GPU-enabled compute
  • ▸Expanded Terraform/Terragrunt patterns and refactored GitHub Actions Terraform CI/CD with separate plan and apply stages, automated project detection, validation and deployment safeguards
  • ▸Supported the cloud architecture and production delivery of ViGenAiR, an AI-powered video advertising platform using Vertex AI Gemini and Google Cloud Video Intelligence, with event-driven processing on Cloud Storage and Eventarc
  • ▸Implemented Prometheus, Grafana, Alertmanager and New Relic, improving alerting, incident investigation and service reliability
  • ▸Strengthened cloud security and governance with IAM controls, identity configuration, deployment isolation and auditable changes
  • ▸Configured Cloudflare DNS and expanded Cloudflare Workers for edge request handling and crawler-related workflows
  • ▸Improved engineering delivery with Blacksmith, GitHub Actions, Greptile and Renovate, and used Linear to track infrastructure work and technical debt
  • ▸Documented platform integrations and disaster recovery requirements, targeting a four-hour RTO and one-hour RPO

Data Engineer

Insight2Actions
Toronto, ON
Mar 2022 - May 2023
  • ▸Advised enterprise clients in regulated environments on cloud infrastructure, DevSecOps, data platforms and production reliability
  • ▸Built and streamlined GCP ETL pipelines with Cloud Storage, Dataflow and BigQuery, improving pipeline reliability through monitoring and validation
  • ▸Supported Kubernetes and cloud-native workloads and enhanced Terraform automation for deployment, security and readiness
  • ▸Applied observability and incident-management practices with platform, security and application teams for production readiness and compliance

Data Engineer

BPCL
Hyderabad, India
Mar 2020 - Mar 2022
  • ▸Ran cloud data and analytics workloads with Python, PySpark, BigQuery, Informatica, Cassandra and Hive
  • ▸Deployed forecasting and predictive analytics workloads using Python, ARIMA and containerized, Kubernetes-based environments
  • ▸Integrated SAP enterprise datasets with analytics and ML pipelines and helped productionize AI/ML services using MLOps practices
  • ▸Created Python automation and Infrastructure as Code for data engineering and operations across AWS, Azure and GCP

Data Analyst

Legacy Designs Inc
Rockford, IL, USA
2019 - 2020
  • ▸Supported data analysis, reporting and engineering workflows for business and technical stakeholders by automating pipelines and integrations

Software Engineering Analyst

Legacy Designs Inc
Rockford, IL, USA
2016 - 2019
  • ▸Improved deployment reliability by 20% by adopting DevOps practices, Infrastructure as Code and cloud technologies for software engineering workflows

10+ years in tech — Working since 2016

For detailed experience history, feel free to get in touch or connect on LinkedIn

05 / skills

Tools I work with

most experience

New Relic

The observability platform I've used most: alerting, dashboards and incident investigation in production, plus Cloud Cost Intelligence for FinOps work.

Observability
New Relic, Prometheus, Grafana, Alertmanager, Datadog, ELK, OpenTSDB
Cloud
AWS, GCP, Azure
Containers
Kubernetes (GKE, EKS, AKS), Docker, Helm, Envoy
Infrastructure as code
Terraform, Terragrunt, Pulumi, Ansible, CloudFormation
CI/CD
GitHub Actions, Cloud Build, Jenkins, GitLab CI, Argo CD
Cost (FinOps)
New Relic Cloud Cost Intelligence, Looker dashboards, Tagging policy, Rightsizing
Data and ML
Airflow, BigQuery, Dataflow, PySpark
Databases
PostgreSQL, Cloud SQL, DynamoDB, Redis, MongoDB
Systems and network
Linux, IAM, VPC networking, Load balancers
Languages
Python, Bash, Go, TypeScript

06 / credentials

Certifications & Badges

Industry-recognized certifications demonstrating expertise in cloud, DevOps, Kubernetes, and infrastructure

View All Badges on Credly
🐧

LFCS: Linux Foundation Certified Systems Administrator

The Linux Foundation

Issued: Nov 2025•Valid until: Nov 2027
LinuxCentOSDisk Partitioning+1
⚓

KCNA: Kubernetes and Cloud Native Associate

The Linux Foundation

Issued: Nov 2025•Valid until: Nov 2027
KubernetesContainersCloud Native+2
🔐

KCSA: Kubernetes and Cloud Native Security Associate

The Linux Foundation

Issued: Nov 2025•Valid until: Nov 2027
Kubernetes SecurityCloud Native SecurityContainer Security
NEW
☸️

CKA: Certified Kubernetes Administrator

The Linux Foundation

Issued: Feb 2026•Valid until: Feb 2028
KubernetesHelmScheduling+3
⎈

CKAD: Certified Kubernetes Application Developer

The Linux Foundation

Issued: May 2025•Valid until: May 2027
KubernetesDockerPython+3
🌐

Professional Cloud Architect Certification

Google Cloud

Issued: Feb 2025•Valid until: Feb 2027
GCPCloud ArchitectureCloud Security+2
📧

Associate Google Workspace Administrator

Google Cloud

Issued: Dec 2025•Valid until: Dec 2027
Google WorkspaceAdmin ConsoleUser Management+1
☁️

AWS Certified DevOps Engineer – Professional

Amazon Web Services

Issued: Mar 2023•Valid until: Mar 2026
AWSDevOpsCI/CD+2

8

Certifications

2

Cloud Platforms

5

Linux Foundation

2027

Valid Until

07 / writing

Write-ups

What I built, how I measured it and what failed

DevOpsCloud RunDatabase

Effortless Database Migrations in Production with Cloud Run Jobs

Master DevOps Project 4: Learn how to automate database migrations in production environments using Cloud Run Jobs and GCP

Read Article

08 / contact

Let's Connect

Questions about Site Reliability Engineering, DevOps, or MLOps? Send me a message.

Get in Touch

Feel free to reach out for collaborations, opportunities, or just a friendly chat. I typically respond within 24 hours.

By submitting this form, you agree to be contacted regarding your inquiry.